Performance diagnosis
Most expensive queries, execution plans, missing indexes and the estimated gain before any change.
Query tuning, observability, high availability, RBAC and tested upgrades, with ongoing support and an SLO the business side understands.
Book a diagnosisAfter go-live, the problem changes nature. The query that flew with two million nodes degrades at twenty; an execution plan changes after an upgrade; the missing index only shows up at peak; and the security team asks who can see which subgraph, with nobody on call who knows the engine.
Performance is an operations decision, not a hardware one.
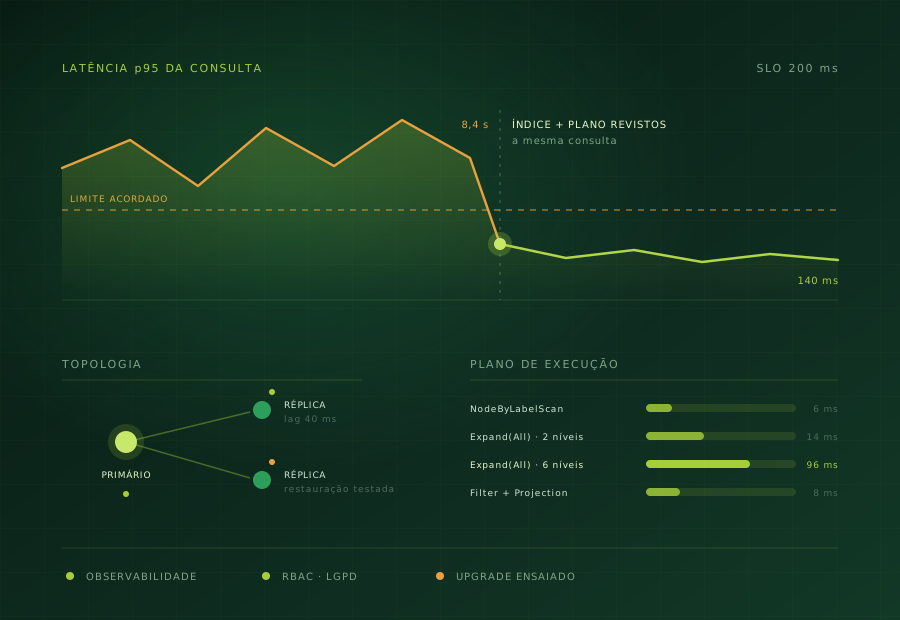
We take over the support of your graph: query and index tuning, observability that links latency to pipeline impact, high availability with tested recovery, access profiles defined with the client, rehearsed upgrades and ongoing support under an agreed SLA.
Talk to an architectEach item is defined before we start and delivered with documentation, so continuity does not depend on us.
Most expensive queries, execution plans, missing indexes and the estimated gain before any change.
Dashboards and alerts that link query latency to operational impact, not just CPU and memory.
High-availability topology, tested backup and a restoration procedure that has been exercised, not just documented.
Agreed on-call, upgrade window, reviewed RBAC and knowledge transfer with every intervention.
Two hours with a graph architect to review model, sources, queries and platform.