Ingestion of what already exists
Connectors for data lake, PostgreSQL, queues and files, with initial and incremental loads separated and versioned.
Incremental ingestion from the data lake and PostgreSQL, auditable entity resolution, idempotent pipelines and query APIs with predictable latency, integrated with your decision engine.
Book a diagnosisLoading an initial dump is easy. What breaks projects is the rest: capturing changes from the data lake and PostgreSQL without duplicating entities, resolving that four records are the same person, reprocessing without taking down queries, and exposing all of it in an API the decision engine can call within the SLA.
The graph is worth what the pipeline sustains.
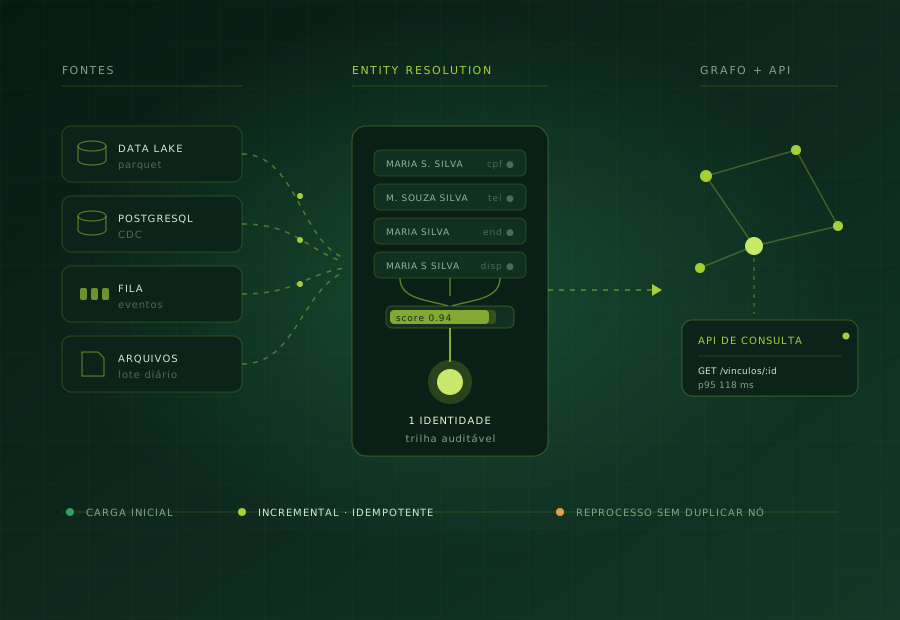
We build the whole pipeline: incremental ingestion from the data lake, PostgreSQL, queues and files; entity resolution with auditable rules and scores; idempotent, reprocessable pipelines; and query APIs with predictable latency connected to the decision engine you already use.
Talk to an architectEach item is defined before we start and delivered with documentation, so continuity does not depend on us.
Connectors for data lake, PostgreSQL, queues and files, with initial and incremental loads separated and versioned.
Matching by document, contact, address and device, with scores, a human review queue and a trail of why two records became one.
Idempotent orchestration: reprocess a day, a source or the entire base without duplicating nodes or losing history.
Query and link-scoring endpoints, versioned and plugged into the existing decision pipeline.
Two hours with a graph architect to review model, sources, queries and platform.